What we can help you with
Faster computations can make it possible to explore more alternatives, use more detailed models or deliver results in time to support a decision. We develop and adapt numerical methods so that simulation tools can make effective use of the parallelism and memory resources available in modern hardware.
We can help you:
- Identify bottlenecks and assess the potential for GPU acceleration in existing software.
- Develop and adapt discretisations, solution methods and preconditioners for parallel computation.
- Improve data structures, memory access and data transfers between CPUs and GPUs.
- Integrate accelerated computational components into simulators and adapt software to different hardware platforms.
- Organise computations for large models, ensembles and extensive parameter studies.
- Evaluate performance, scalability and numerical accuracy on representative problems.
Does your simulator take too long to run, or are computational limits preventing you from carrying out the studies you need? Contact our Applied Computational Science research group.
Connecting mathematics, algorithms and hardware
Effective GPU utilisation depends on how computations are formulated and organised. A method that performs well on a CPU may have dependencies or memory access patterns that limit its performance on a GPU. In some cases, choosing a different numerical method offers greater gains than optimising the implementation of the original one.
We therefore consider model formulation, algorithms and implementation together. This may involve reordering computations, combining operations, reducing data movement or selecting solution methods that expose more parallelism. The aim is to reduce overall computation time while meeting requirements for accuracy and robustness.
From local computations to coupled equation systems
Explicit methods for transport and wave propagation often involve many local computations that can run in parallel. Efficient grid organisation and effective use of memory bandwidth are central to their performance. We have extensive experience with these methods for conservation and balance laws, including applications to water flows.
Implicit simulators also require the solution of large, coupled equation systems. Their performance depends on the interplay between system assembly, sparse matrix operations, iterative solvers and preconditioning. We work on adapting these components to GPUs and integrating acceleration into the simulator's overall computational workflow.
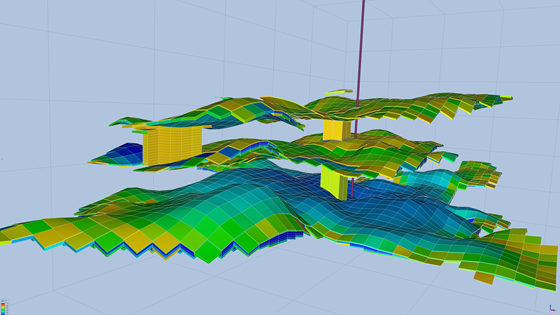
Our work on GPU acceleration for OPM Flow illustrates how we develop computational components within an established reservoir simulator.
One large model or many simulations
Computational demand can arise from the size of a single model or from the number of times it needs to be run. Uncertainty analysis, data assimilation, model calibration and optimisation often require many related simulations. It is therefore important to consider both parallelism within each simulation and the distribution of independent runs.
We adapt the computational approach to the task and the available resources. For time-critical applications, the priority may be to obtain a result as quickly as possible. For ensemble studies, it may be more important to complete as many simulations as possible within a given time and resource budget.
GPU Ocean uses GPU acceleration to run ensembles of ocean models, supporting uncertainty analysis and the integration of simulations with observations.
Integration and portability
An accelerated component must work effectively with the rest of the software. Data transfers between CPUs and GPUs, synchronisation and repeated conversions can offset the gains from fast individual operations. We therefore examine the complete computational workflow and assess which data and operations should remain on the accelerator.
We also develop software structures and abstractions that support different hardware platforms without requiring entirely separate implementations of the same numerical method. The choice of tools and programming model must balance performance, portability and future development needs.
Performance that matters in practice
A fast computational kernel is valuable when it improves the performance of the overall simulation. We therefore measure both individual components and complete simulation runs, accounting for problem size, memory use, convergence and data transfers.
Comparisons must use equivalent requirements for numerical accuracy. Changes in arithmetic precision, solver tolerances or algorithms can affect both runtime and results. We use representative test problems to assess the benefits and establish when a particular approach is advantageous.
More than two decades of GPU computing
We were among the early pioneers using programmable graphics cards to solve conservation and balance laws numerically in the early 2000s. Our introductory chapter from 2007 describes how high-resolution numerical methods can be adapted to graphics processors.
Hardware and development tools have changed substantially since then. The underlying lesson remains relevant: achieving good performance requires an understanding of both the mathematical problem and how the computations are executed. We continue to apply this combination in the development of simulators and numerical components for research and industry.
Further reading
- Hagen, T. R., Henriksen, M. O., Hjelmervik, J. M. and Lie, K.-A. (2007). How to Solve Systems of Conservation Laws Numerically Using the Graphics Processor as a High-Performance Computational Engine. In Geometric Modelling, Numerical Simulation, and Optimization, pp. 211–264. An early contribution on the interplay between numerical methods and GPU computing.
- Accelerated performance with GPUs for OPM Flow. A project on GPU acceleration for reservoir simulation.
- GPU Ocean. GPU-accelerated software for ensembles of ocean models.